
AGI Blueprint Visual Thought, Meta-Cognition & Human-Level Architecture - 2025 by Derek Van Derven - HTML preview
Download the book in PDF, ePub, Kindle for a complete version.
Training Corpus and Knowledge Base
The multimodal cognitive system is pretrained and continuously refined using the following data sources:
Language and Conceptual Pretraining
- **Corpus**: Massive multilingual datasets including Wikipedia, Common Crawl, Project Gutenberg, ArXiv abstracts, and curated philosophical, scientific, and technical literature. - **Purpose**: Pretraining on language comprehension, metaphors, context handling, question answering, symbolic mappings.
- **Method**: Transformer-based architectures trained using masked token prediction (BERT-style) and autoregressive prediction (GPT-style).
Symbolic and World Knowledge Graphs
- **Knowledge Graphs**: ConceptNet, WordNet, DBpedia, Wikidata
- **Symbol Mapping**: Entities and relationships stored in graph form and linked to visual and physical models via symbolic anchors.
- **Example**: “Apple” in ConceptNet is linked to “fruit,” “eat,” “grow on trees” → these are attached to mesh assets and robot action plans.
Visual and Simulation Pretraining
- **Datasets**: ImageNet, OpenImages, ShapeNet, Google Scanned Objects
- **Use**: To link language to image → mesh → scene composition.
- **3D Mapping**: Text-to-Image → Diffusion Meshify pipeline generates missing objects when not in asset database.
Reinforcement and Episodic Learning
- **Environment**: Unity/Unreal simulated world
- **Method**: Self-play, exploration-based reinforcement learning (RL) using intrinsic motivation and goal scoring.
- **Data Storage**: All completed tasks are stored with scene IDs, result states, contradictions found, and self-assessments.
Ethical Constraints and Filters
- **Training**: Trained on real-world ethical scenarios from law, philosophy, and cultural datasets.
- **Method**: Supervised fine-tuning + symbolic rule overlay + adjustable value systems.
- **Execution**: Behavior can be altered based on loaded ethical schema or user-defined role settings.
Avatar-Based Pretraining and Simulated Embodiment
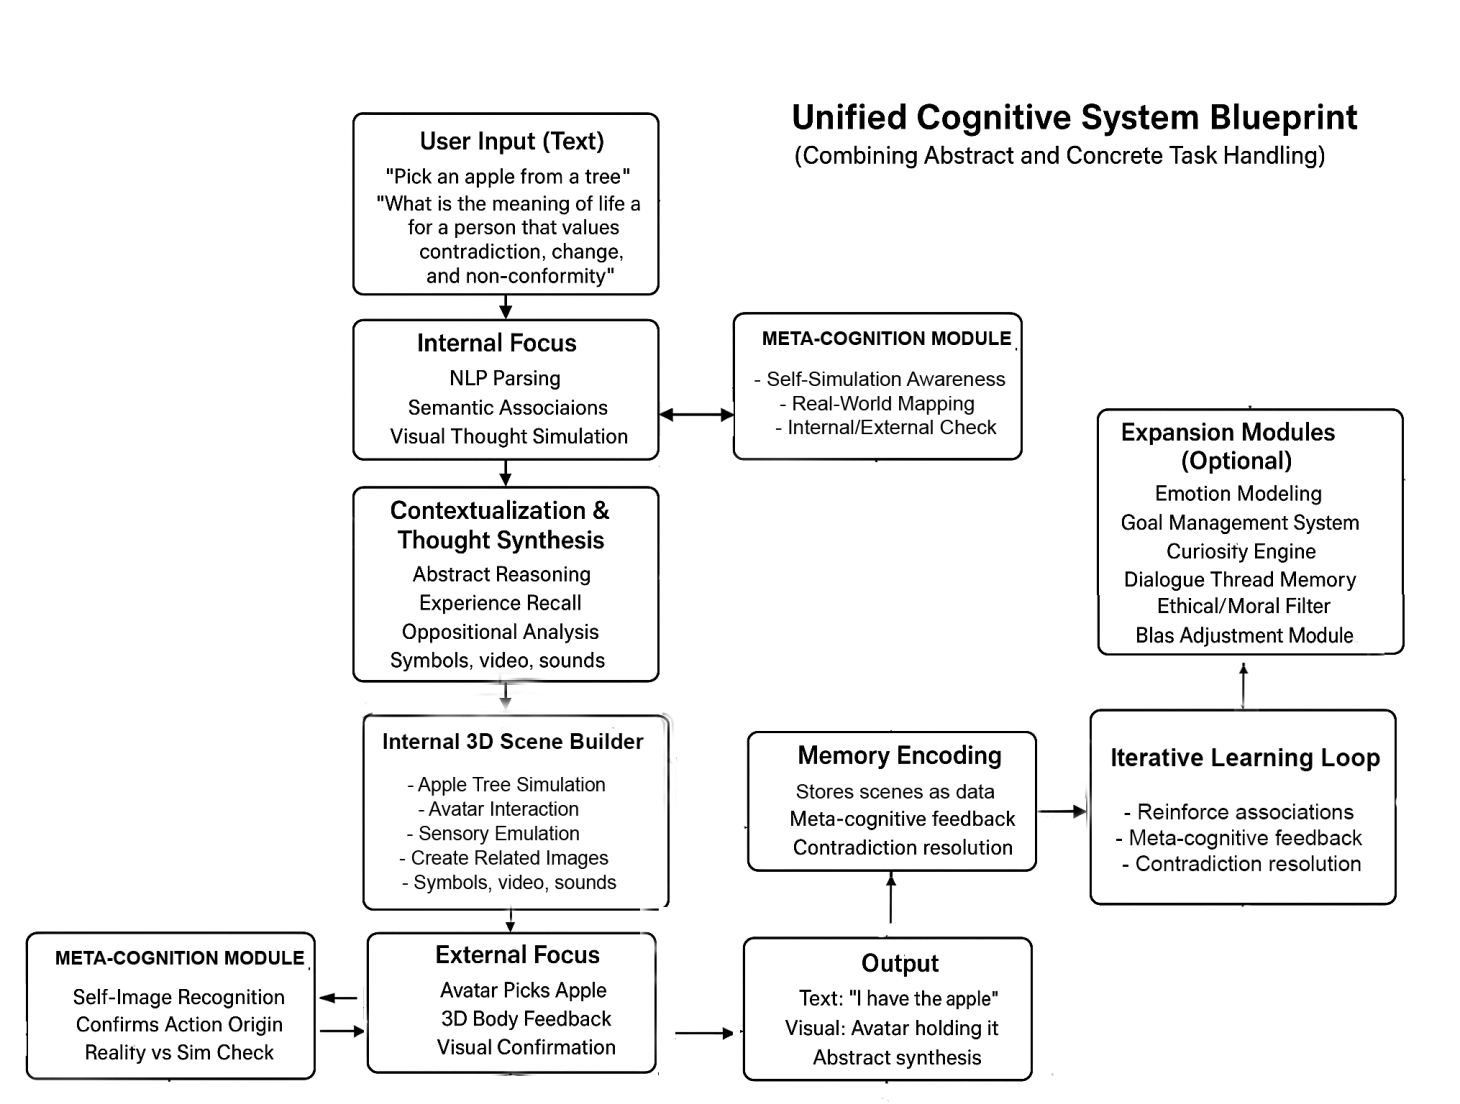
Most of the multimodal cognitive system's foundational learning and symbolic integration will occur within a **virtual avatar**, operating in simulated environments before being embedded in any physical robotic platform. This allows the system to develop core competencies — visual reasoning, task execution, contradiction detection, memory encoding, and philosophical response generation — in a safe, accelerated, and scalable environment.
*Transition from Virtual Avatar Training to Physical Embodiment, including data
flow and learned behavior transfer.*